What is A/B Testing? The Complete Guide
Learn how to plan an A/B test, choose a hypothesis and metric, estimate sample size, run the experiment, and interpret uncertain results.
October 7, 202611 min read
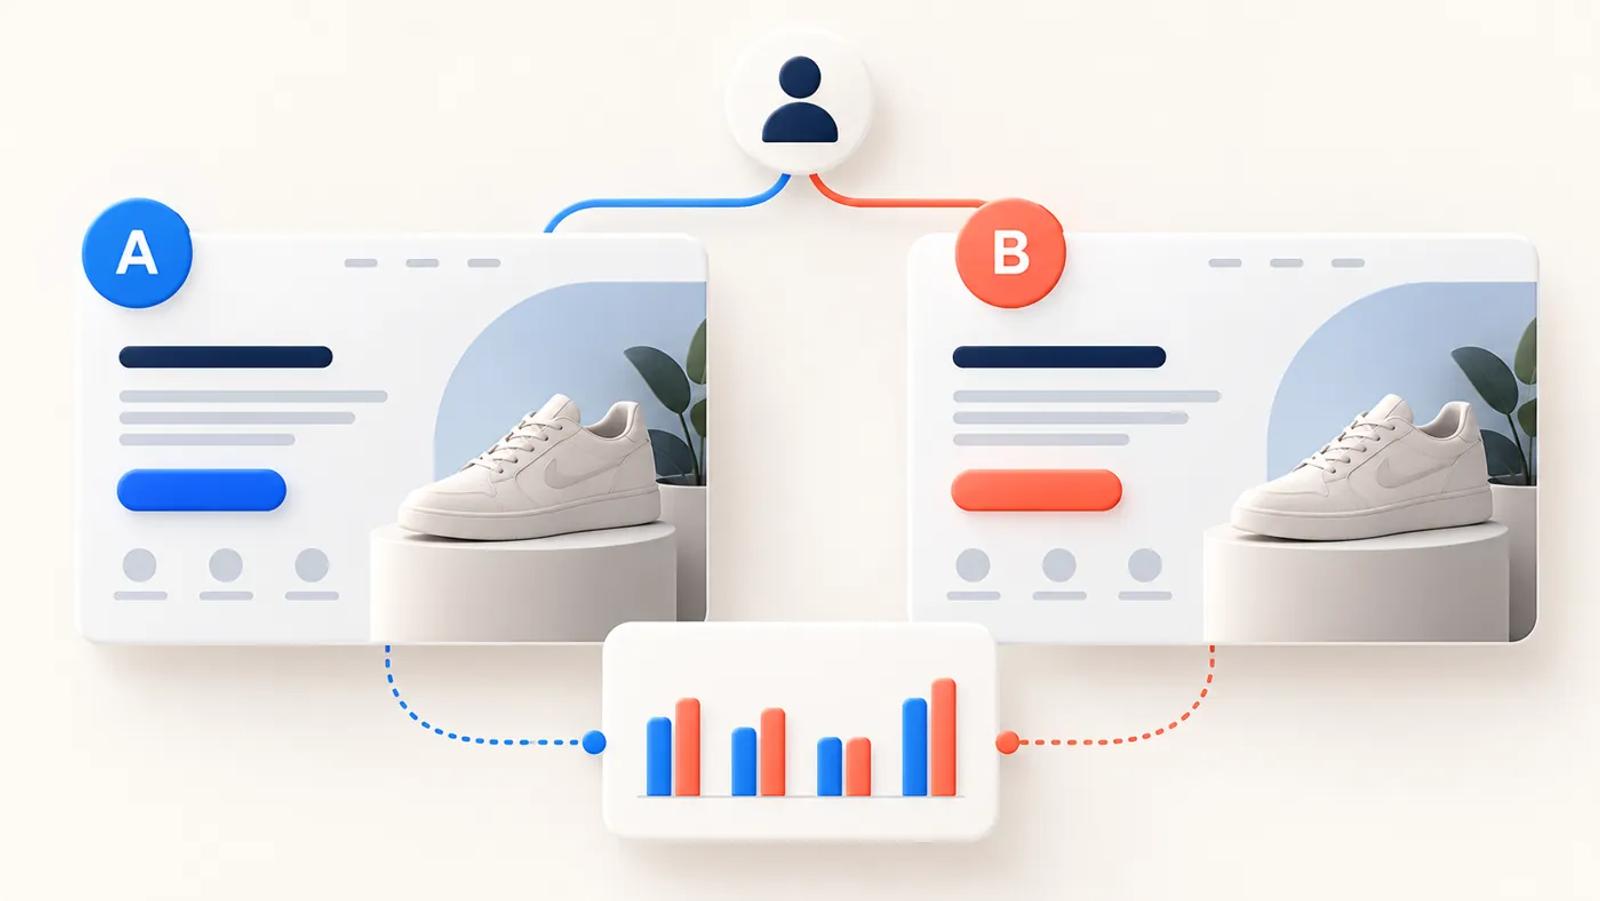
A/B testing compares two versions of an experience by randomly showing them to different users during the same period and measuring a predefined outcome. Version A is the current experience; version B contains a change. The goal is not simply to pick the larger number. You need to estimate whether the change made a difference, how uncertain that estimate is, and whether the difference matters enough to justify a business decision.
You can test a headline, pricing presentation, signup flow, email subject line, or product feature. A trustworthy experiment needs a hypothesis, primary metric, randomization unit, sample plan, and decision rule defined before results arrive. Without them, it is easy to mistake noise for evidence.
What is A/B testing and how does it work?
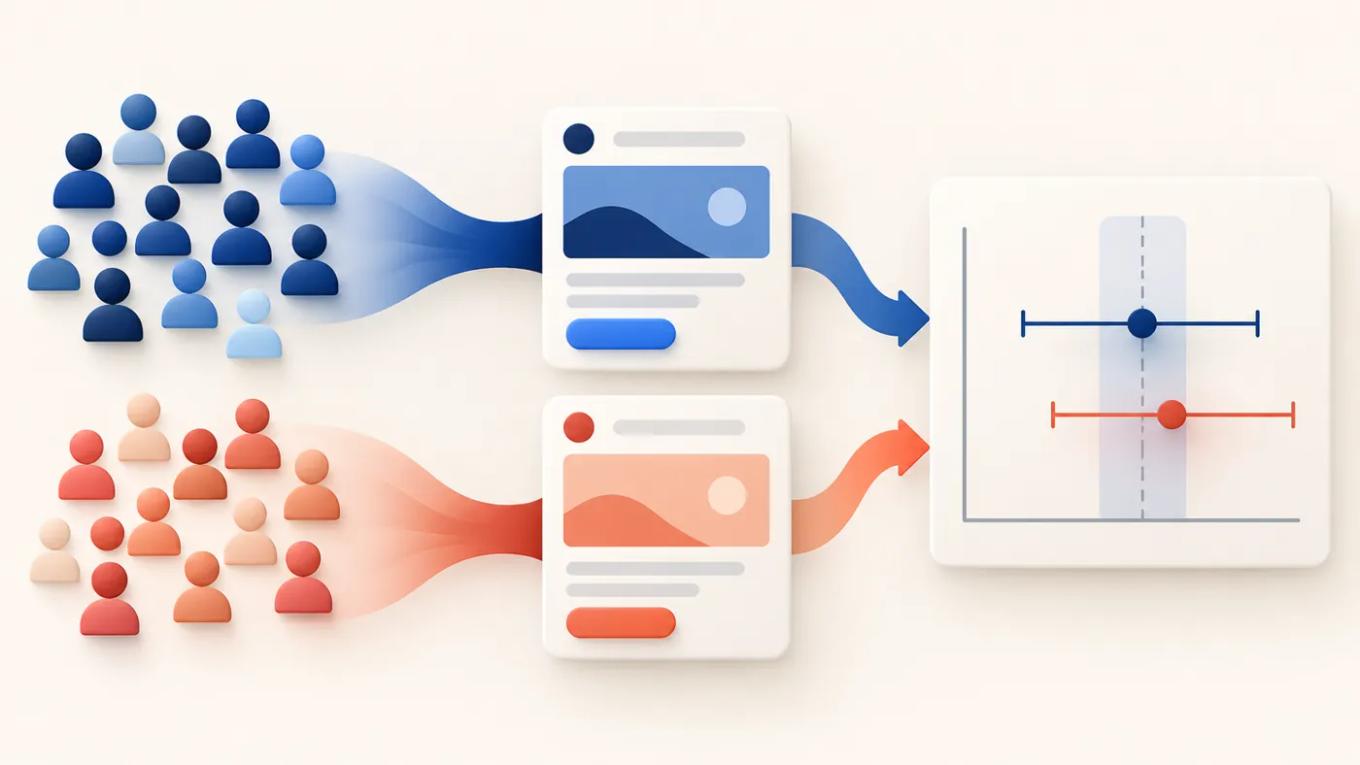
An online controlled experiment such as an A/B test randomly assigns users to a control group and a variant group. The control sees the current experience; the variant sees the change. Assignment should remain consistent. If someone sees both experiences across sessions, their behavior may contaminate the comparison. Running both groups at once also balances outside conditions such as campaigns and seasonal demand.
Imagine an ecommerce team wants to know whether earlier delivery information increases checkout completion. The control is the existing page; the variant moves the delivery estimate higher. Users are randomly assigned while both versions run at once, with completed orders per eligible user as the primary metric. This example is hypothetical, not a reported result or a lift prediction.
An A/B test is different from a before-and-after comparison. Comparing this week with last month cannot separate a design change from campaigns, traffic mix, or demand. Random assignment and a concurrent control reduce these confounding factors, providing a stronger effect estimate. They cannot eliminate measurement errors or poor implementation.
The table below distinguishes A/B testing from approaches that may look similar. The difference is not only the number of options. It also depends on the question you need to answer and how traffic is allocated. Choosing the design early helps avoid asking the wrong method to answer your question.
Method | What is compared? | Best fit | Main limitation
A/B test | Control and one variant | A focused hypothesis about one change | Other changes can still affect the result
A/B/n test | Control and several variants | Comparing a few planned alternatives | Each arm gets less traffic and creates more comparisons
Multivariate test | Combinations of several elements | Measuring interactions when traffic supports it | The number of combinations grows quickly
Before-and-after | Outcomes in different periods | Monitoring or rough exploratory comparison | Does not establish causal impact by itself
Multi-armed bandit | Traffic allocation that adapts to performance | Ongoing distribution optimization | May not answer the same estimation question as a fixed experiment
This distinction helps with method selection, though product vendors may use labels differently. A bandit can shift more traffic toward options that currently appear better, which can be useful for continuous allocation. If you need an unbiased estimate of how much a variant changes an outcome, confirm that the design and analysis method match that goal before launch.
When should you run an A/B test?
Start with a concrete user problem or business objective. If product page visitors rarely add items to the cart, behavioral data and user research can help identify why. An experiment can then test a specific change suggested by that evidence. Replace “make the button stand out” with a testable statement about the friction to reduce and behavior to change.
Not every decision needs an A/B test. A low traffic page may take too long to measure a modest effect, and legal, accessibility, or obvious bug fixes should not wait. Interviews, usability studies, and analytics can help diagnose the issue first, but they do not provide the same causal evidence as a controlled experiment.
Compare the value of a test with its cost and time. A checkout rebuild may need stronger evidence than a small email subject line change. Prioritize likely impact, evidence quality, implementation effort, and achievable sample volume. The question should be important enough to change a decision and narrow enough to measure.
How to run an A/B test
A useful workflow follows a clear order: define the problem, validate measurement, write the hypothesis and decision criteria, implement the variant, and evaluate results against the plan. You can adapt the steps below to a marketing page, a product flow, or a campaign. Assigning an owner and a verifiable completion criterion to each step helps prevent an experiment from being configured in a tool and then forgotten.
- **Choose the question.** Find recurring friction in analytics, search, support, or research data. Tie the problem to a page, segment, or step in a user journey.
- **Write a hypothesis.** Use a structure such as “Users in X face Y problem. Change Z may affect metric M in this direction because…” Ground the reason in existing evidence.
- **Choose one primary metric.** Define the behavior that represents success and how the event will be counted. Do not change the primary metric after seeing results.
- **Add guardrail metrics.** Check whether orders increase while refunds, errors, load time, or average order value deteriorate. Guardrails do not replace the primary success metric.
- **Select the design and unit of assignment.** Randomization may happen by visitor, user, account, or session. Decide which unit must remain in the same variant throughout the experiment.
- **Plan sample size and stopping.** You need the baseline rate, a meaningful minimum effect, and statistical settings. Verify that the calculator matches the test type and analysis method.
- **QA the implementation.** Check each variant on desktop and mobile, validate events, currency, redirects, assignment, and reporting with test traffic or an A/A check.
- **Record the result and learning.** Add the effect estimate, uncertainty, guardrails, rationale, dates, and next step to an experiment archive.
The workflow is not a universal hypothesis template. It ensures the team shares one question, metric, and success condition. If a change may work differently by device or user group, plan that analysis before launch. Searching many subgroups after results arrive increases the chance of finding a pattern by coincidence.
How to choose a hypothesis and metric
A hypothesis should be observable. “The new design will look more modern” is subjective. “Showing delivery timing near the call to action may reduce uncertainty and increase completed orders per visitor” makes a measurable prediction. If it is wrong, you learn that the assumed barrier may not explain behavior.
Choose a primary metric close to the value the change should create. Email opens may be an early signal, but a sales goal also needs clicks or revenue. Clicks can rise while qualified signups fall. Consider the downstream outcome and define the measurement window and denominator before launch.
Document whether users can be counted more than once. Conversion definitions may use users, sessions, or impressions, which are not interchangeable. Align the experiment report with finance or analytics before deciding. Keep the denominator consistent across teams and tools. Document it in the analysis plan.
Sample size and test duration
There is no universal sample size. The baseline rate, minimum effect, error tolerance, statistical power, and number of variants affect the observations needed. Smaller differences generally require more data. Treat a calculator estimate as the result of its inputs and method, not proof that a fixed visitor count is always enough.
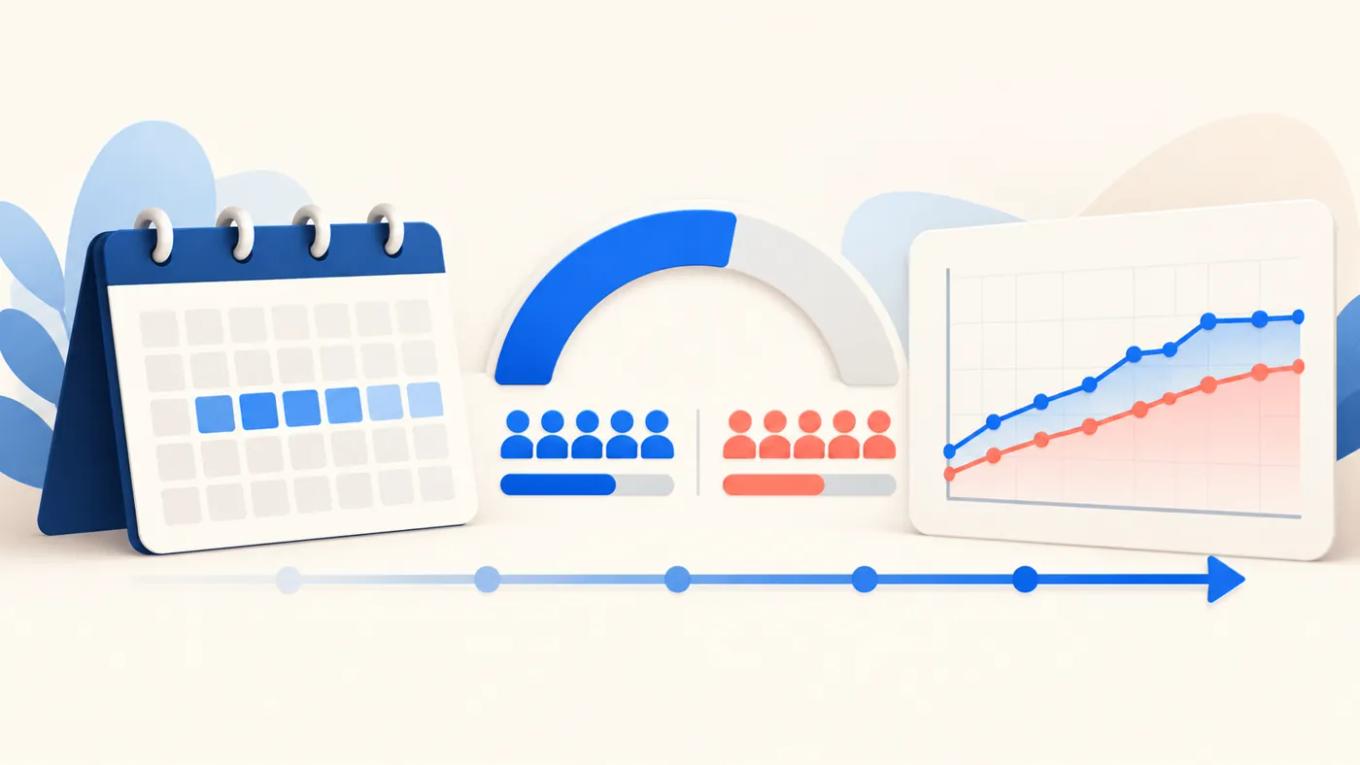
The minimum detectable effect, or MDE, is the smallest difference worth detecting. A very small MDE increases sample needs; one set too large can miss modest improvements. Do not choose it simply to make the test finish faster. Weigh it against implementation cost, user impact, and decision value.
Use a baseline from a relevant period and population. Campaigns, pricing, product mix, and seasonality can shift it. Unequal allocation or extra variants slow data collection, so more options do not automatically create better learning. Check recent changes in traffic mix.
Set duration using the planned sample and relevant business cycles. If demand changes on weekends, observe both weekdays and weekends. Campaigns, paydays, or inventory may also affect outcomes. If the end date arrives before the sample target, follow the extension rule you defined in advance.
How to interpret A/B test results
Check data quality first. If the observed allocation between variants differs materially from the intended split, you may have a sample ratio mismatch, or SRM. It can indicate a broken event, redirect problem, device filter, bot traffic, or users switching between variants. Do not trust the result until you understand the cause. Amplitude's SRM troubleshooting guide explains why the discrepancy can make experiment results suspect.
Then review the effect estimate, uncertainty interval, and decision threshold together. Statistical significance describes how the observed data fit a selected model and its assumptions. It does not prove that a change is certainly correct or important to the business. A small but consistent effect may not justify its implementation cost. A large-looking difference with a wide uncertainty interval may need more evidence before you commit.
Do not decide from a green “winner” label alone. Repeatedly checking and stopping when results look favorable can raise false positive risk if the method does not support that decision. With a fixed-sample plan, follow the sample and stopping rule. For sequential testing, use an analysis system that accounts for repeated looks. Firebase documentation shows that methods are platform-specific; one tool's rules may not transfer to another.
Common mistakes and practical fixes
The table summarizes operational choices that often undermine a test and how to reduce their impact. The goal is not to make every team adopt an elaborate statistical process. It is to make problems that could lead to a wrong decision visible before the experiment ends.
Mistake | Likely effect | Safer approach
Stopping as soon as results look favorable | Raises false positive risk | Set the sample plan and stopping rule before launch
Changing multiple elements and calling it an A/B test | Leaves the cause of an effect unclear | Start with one hypothesis or use a design that measures interactions
Looking only at click-through rate | Can miss downstream quality loss | Track business outcomes and guardrails alongside the primary metric
Skipping assignment and event QA | Broken data can look like a real difference | Validate variants and events before launch
Searching many metrics and subgroups | Increases chance findings | Preselect a primary metric and limit subgroup analysis
A report may not expose every issue. Code that fails in one browser can hide data loss behind a balanced split. Test devices, browsers, languages, and sessions before launch, then monitor errors and event volume. Check the event schema and user journey.
No clear difference can still be informative. A narrow interval may rule out a meaningful effect; a wide interval means the result is inconclusive because the sample may be small or the data noisy. That distinction helps decide whether to rerun, refine the hypothesis, or stop.
What if traffic is low?
Low traffic limits which effects you can measure and how quickly you can measure them. Small changes may be unrealistic to detect. If a test would take months, focus on a higher traffic journey, evaluate a larger change, or use user research to discover problems. These methods do not provide the same evidence as a controlled experiment, so record the distinction.
A high-volume event may provide an early signal without revealing downstream outcomes such as cancellations or refunds. Metrics like revenue per user take longer to mature. Connect early indicators to later results and do not call a short-term increase a success if it fails to align with the business outcome.
Choosing an A/B testing tool
Compare price and the visual editor with assignment, persistent identity, collision management, statistical methods, accessibility, and performance impact. Confirm analytics integration, privacy requirements, and channel support. A tool cannot repair a weak design, but it should support your analysis approach.
Google Analytics does not assign variants as a standalone A/B testing tool across every platform. Google's Analytics help documentation says GA4 tests require a third-party experiment integration. Firebase A/B Testing uses Google Analytics events for mobile configuration and messaging. Match a tool to your channel, decision, and event infrastructure.
Use what you learn in the next test
Shipping a variant is not the only measure of success. Archive the audience, dates, metric, assumptions, hypothesis, implementation, outside conditions, data checks, and decision rationale. Record inconclusive and negative results too; they can improve later hypotheses and prevent repeated assumptions.
After shipping, monitor business metrics because production traffic and behavior can differ from the experiment. Roll out gradually when possible and watch errors and guardrails. Use the site's marketing and conversion calculators for baseline rates, and consult the GEO checklist for related measurement work.
A/B testing grounds a business decision in a controlled comparison of randomly assigned users. Useful evidence requires a sufficient sample, reliable measurement, a predefined metric, and a sensible decision rule. The answer should be more informative than “B won.” Explain which change appeared to work, under what conditions, how uncertain the result remains, and how the learning changes the next decision.