Control group in A/B testing: size, holdouts and checks
What a control group is, how it differs from the treatment group, how large it should be, holdout groups, incrementality, SRM and A/A tests.
13 min read
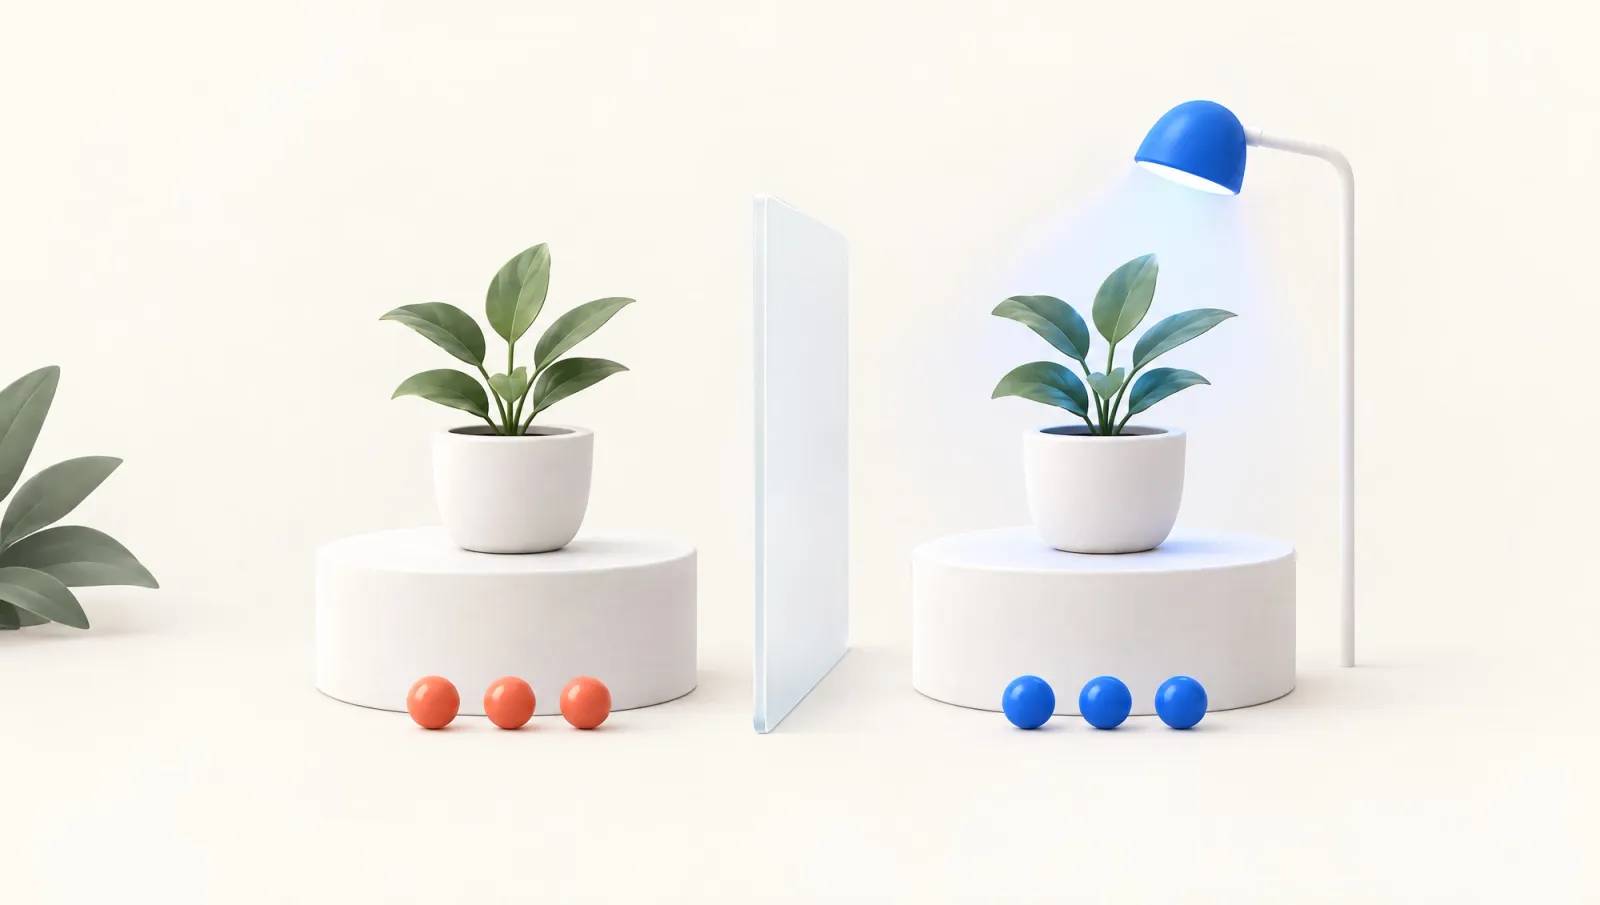
A control group is the group in an experiment that does not get the change being tested. It is the baseline the results are compared against.
In an A/B test, the control group sees the current version of the site or app and the treatment group sees the new one. Because both groups are formed at random and run over the same period, the difference between them can be attributed to the change.
This guide covers what a control group is and why it has to run at the same time as the treatment. It also covers how large it should be, how it differs from a holdout group and how to tell when it has broken. Sample size and reading results have their own guides, linked where they come up.
What is a control group?
A control group is the comparison group that represents what happens without the change. The term comes from clinical research.
The US National Cancer Institute's dictionary defines it for a clinical trial. There, it is the group that does not receive the new treatment being studied. It is compared with the group that does, to see whether the new treatment works.
The UK Treasury's evaluation guidance applies the same idea to public policy. A comparison group formed by random allocation stands in for what would have happened without the intervention.
Online experiments follow the same logic. Ronny Kohavi and co-authors wrote a guide to controlled experiments on the web. In it, users are randomly assigned to one of two variants.
The control is commonly the existing version, and the treatment is usually the new version being evaluated. The control group's job is to show what the treatment group's result should be compared with. Without it, when you see a lift you cannot tell whether it came from the change or from something else.
Control group vs experimental group
The only difference between the control group and the experimental group (also called the treatment group) should be the change being tested. The treatment group sees the change and the control group does not. Everything else needs to be the same for both: the same period, the same traffic sources, the same prices and the same campaigns.
An example from the pitfalls paper by Microsoft's experimentation team shows how sensitive this is. In an experiment testing headline placement on the MSN homepage, both groups were meant to see the same headlines in a different order. However, one headline was different for a seven-hour period.
With those seven hours in the analysis the treatment was significantly better than the control. Once they were removed there was no difference. When the control and treatment differ in more than one way, what you measure is no longer the change you meant to test.
Control and variant in an A/B test
The control group in A/B testing is usually A, and the variant is B. Kohavi and co-authors treat the control as a special variant: the existing version that every new treatment is compared against.
It has a second job too. If a bug turns up, the experiment is aborted and all users go back to the control. That makes the control the safe fallback as well.
In an A/B/n test with several variants, all of them are compared with the same control. The control does not have to be the live version of the site, but in most tests it is. The real A/B testing examples show what a control and a variant look like in practice. For the overall setup of a test, including the hypothesis and the choice of metric, see the complete A/B testing guide.
Random and concurrent assignment
Why does the control group have to run at the same time? Because external factors that could move the result are only spread evenly when both groups are measured over the same period.
The sample ratio mismatch (SRM) paper from Microsoft's experimentation team says it directly. External factors such as seasonality, other feature launches and competitors' moves are distributed evenly between control and treatment. If you take the control from last month and the treatment from this month, those factors hit only one side.
That is why a before/after comparison is weak evidence. According to the UK Treasury's guidance, before/after designs without a comparison group give a weak estimate of what would have happened otherwise.
Any number of factors could explain the change in the "after" data. When conversion rises after a redesign, a campaign that started the same week or a seasonal effect could explain the rise just as well. The A/B testing guide covers this in more detail in its section on before/after comparisons.
Random assignment matters as much as timing. In Kohavi and co-authors' words, the key is "random": no factor can be allowed to influence which group a user lands in. Suppose you choose the groups yourself, for example by putting loyal customers in the new version and everyone else in the control. Then the groups differ from the start, and the difference you measure reflects that.
Persistent assignment and the unit of assignment
A user assigned to a group at the start of a test should stay in it for the whole test. The first chapter of Kohavi, Tang and Xu's book describes this as persistent assignment: a user receives the same variant across multiple visits. If assignment is redone on every visit, the same person sees both versions and the control stops being a control.
Choose the unit of assignment up front as well. You can assign by visitor, signed-in user or account.
If the outcome you measure is per person, assignment should be per person too. In business-to-business (B2B) products, where colleagues use the same product, assignment is often done per account. When people in one account see different versions, it confuses them and leaks between groups.
How large the control group should be
Control group size directly sets how long a test takes. An even split gives the fastest answer, but teams sometimes want a small control or a small treatment.
What size should a control group be?
In a two-group test, the control group should be the same size as the treatment group. In their 2009 guide, Kohavi and co-authors recommend that 50% of users see each variant. This maximizes the power of the experiment and minimizes its running time.
The same guide notes that an experiment run at 99%/1% has to run about 25 times longer than one run at 50%/50%. This slowdown follows the rule of thumb 1 ÷ (4 × p × (1 − p)), where p is the smaller group's share. The table applies that rule to common splits and assumes everything else stays fixed.
Split (larger / smaller group): 50/50
- Smaller group's share
- 50%
- Run time vs 50/50
- 1×
Split (larger / smaller group): 60/40
- Smaller group's share
- 40%
- Run time vs 50/50
- About 1.04×
Split (larger / smaller group): 70/30
- Smaller group's share
- 30%
- Run time vs 50/50
- About 1.19×
Split (larger / smaller group): 80/20
- Smaller group's share
- 20%
- Run time vs 50/50
- About 1.56×
Split (larger / smaller group): 90/10
- Smaller group's share
- 10%
- Run time vs 50/50
- About 2.78×
Split (larger / smaller group): 95/5
- Smaller group's share
- 5%
- Run time vs 50/50
- About 5.26×
Split (larger / smaller group): 99/1
- Smaller group's share
- 1%
- Run time vs 50/50
- About 25×
| Split (larger / smaller group) | Smaller group's share | Run time vs 50/50 |
|---|---|---|
| 50/50 | 50% | 1× |
| 60/40 | 40% | About 1.04× |
| 70/30 | 30% | About 1.19× |
| 80/20 | 20% | About 1.56× |
| 90/10 | 10% | About 2.78× |
| 95/5 | 5% | About 5.26× |
| 99/1 | 1% | About 25× |
The curve steepens fast after 80/20. A 60/40 split costs almost nothing, while 90/10 makes the test run nearly three times as long. That is why GrowthBook's power documentation says to use the smaller of the two sample sizes when groups are unequal. To work out how many visitors you need, use the sample size guide and the A/B test sample size calculator.
There is one legitimate reason to start with a small group: a ramp-up. Kohavi and co-authors give the example of starting a risky change at 0.1% and ramping it to 0.5%, 2.5%, 10% and then 50%. The point is not measurement but catching a bug while few users are affected.
Microsoft's pitfalls paper adds a warning: pooling data from periods with different split ratios can point to the wrong winner because of Simpson's paradox. Base the real comparison on the period after the ratio is fixed.
The risk of a large shared control
Comparing several variants with one large control group looks attractive. Kohavi and co-authors' 2009 guide noted that when you only care about comparing each treatment with the control, making the control larger can improve power. In the 2022 paper "A/B Testing Intuition Busters", the same authors reach a more cautious conclusion and recommend against a large shared control.
They give three reasons. Cookie churn causes a larger share of users in the smaller variants to be exposed to other variants.
When distributions are skewed, a t-test on an unequal split cannot hold its nominal error rate. In the paper's simulation, an A/A test split 10% to 90% had a one-tail false positive rate of 5.42% against a nominal 2.5%. And the gain is small: for two to four treatments, the variance reduction from the optimal shared control size is under 10%.
Holdout groups and control groups in campaigns
A control group lives for the length of one test. Some questions are too long-term for a single test to answer, and a holdout group fills that gap.
Control group vs holdout group
A holdout group is the control group for everything shipped over a long period, not for a single test. A joint paper on this was written by experimentation teams from Airbnb, Amazon, Booking.com, Google, LinkedIn, Microsoft, Netflix and others. It describes a long-term holdout as a random sample of users who do not get updates. That group acts as the control against the features shipping to everyone else.
Confidence, Spotify's experimentation platform, has a glossary that sums up why a holdout is needed. Ten experiments that each showed a 1% improvement in a metric don't guarantee a 10% cumulative gain. A holdout measures what those features do together and over the long run.
The holdout sizes in tool documentation differ. Statsig's holdout documentation says holdouts typically withhold 1% to 2% of users and recommends running one for three to six months. GrowthBook's default is 5%, Optimizely says typically up to 5%, Amplitude suggests between 1% and 10%, and Spotify says typically 1% to 5%. These are each tool's own guidance, not a universal rule.
A holdout also has costs. The joint paper notes that maintaining a code fork that is not updated for a long time usually incurs a lot of engineering cost. GrowthBook's documentation points out that holdout users miss out on improvements. And the larger the holdout, the less traffic is left for other tests, which then take longer.
Control groups in campaigns and incrementality
Control groups are not limited to site and app tests. Ad, e-mail and push campaigns use them to measure incrementality, the result that would not have happened without the campaign.
Google Ads' Conversion Lift documentation describes it as comparing two groups. A treatment group sees the ads, and a control group is held back from them. Incremental conversions are calculated as treatment conversions minus control conversions. The same page warns that very large relative lifts can easily occur for brands with little conversion activity in the control group.
Meta's lift study documentation likewise creates a randomized test group that sees the ads and a control group that doesn't. Braze's Global Control Group sets aside a share of users who receive no campaigns, so the overall impact of messaging can be measured over time.
Problems that break a control group
How do you know a control group is broken? Two signs are the most reliable. The first is whether the groups filled at the planned ratio.
Another is whether two groups seeing the same experience produce the same result. A third sign is whether users in one group affect the other. Run these checks however good the result looks.
Sample ratio mismatch (SRM)
A sample ratio mismatch (SRM) is when the number of users in each group differs from the planned ratio. According to Microsoft's SRM paper, an SRM in most cases completely invalidates experiment results.
In the paper's example, 821,588 versus 815,482 users, a 50.2/49.8 ratio, looks close. Yet it is far enough from 50/50 that the probability of it happening by chance is less than 1 in 500,000.
The paper reports that about 6% of experiments at Microsoft showed an SRM. That rate applies to Microsoft's experiments only.
An MSN example in the same paper shows how an SRM can flip a result. The most engaged users in the treatment group were classified as bots and removed from the analysis by a bot-detection algorithm. Once that was corrected, the result reversed and the right decision was to ship the feature.
A chi-squared test is used to detect an SRM. GrowthBook runs this test on its results screen and shows a warning when the p-value is below 0.001.
Optimizely, on the other hand, says an imbalance does not mean results are immediately invalid. Because the sources disagree, the safest path is not to act on a result until you have found the cause of the imbalance.
A/A testing
An A/A test is a test in which both groups get the control experience. As Kohavi and co-authors describe it, the experimentation system assigns users to two groups as usual but shows both exactly the same experience.
At a 95% confidence level, a significant difference between these identical groups should turn up about 5% of the time. If it turns up much more often, something is wrong with assignment or measurement.
Microsoft's pitfalls paper notes that a logging test checks that data is recorded. It will not catch users being assigned to the wrong variant, while an A/A test can. The guide to statistical significance in A/B testing explains significance and false positives in more detail.
Spillover and network effects
The control group must not be affected by users in the treatment group. The joint paper calls this a network interaction, where one user's behavior is influenced by another's. As a result, users in the control are affected by what the treatment group does.
In that case, the paper says, the control group is a control group in name only. Ignoring the interaction gives a biased estimate of the effect.
The risk is highest where users affect each other, such as social networks and marketplaces. The paper describes how Lyft reduces it by randomizing across regions or time windows, at the cost of a noisier estimate.
Before you start a test, settle these points for the control group:
- Unit of assignment: Visitor, user or account, at the same level as the outcome you measure.
- Split: 50/50 for a two-group test. If you choose another ratio, work out what it does to the run time.
- Period: Both groups run on the same dates under the same campaigns.
- One difference: Apart from the tested change, everything both groups see is the same.
- Checks: Monitor SRM throughout, and run an A/A test first on a new tool or setup.
A test that passes these checks is ready to be read. To see whether a difference can be put down to chance with your own numbers, use the A/B test significance calculator.

Related tools
- A/B Test Sample Size CalculatorCalculates the required sample size per A/B test variant.
- A/B Test Significance CalculatorTests whether the difference between two variants is statistically significant.
- A/B Test LibraryA structured experiment library. Each scenario keeps the hypothesis, the one variable that changes, the decision metric, guardrails and setup risks together.
What to read next
 November 14, 2026Funnel optimization: how to diagnose each step and test the fixFunnel optimization starts with lost users counted per step and weighed by later steps. Segment the funnel, then test one change against a control group.
 November 14, 2026How to increase form conversions: measure each field, fix, then testTo increase form conversions, measure which field people leave at with GA4 events, fix the problem in that field and test the change against a control group.
 November 14, 2026How to run a CRO audit: tracking, then the drop-off and its causeA CRO audit runs in order: match GA4 purchases to your orders, find the drop-off in step data, look for its cause, then turn findings into ranked tests.